In 2026, building enterprise AI applications requires far more than writing clever English prompts in a playground. When deploying generative AI across thousands of internal employees and customer-facing web apps, organizations encounter severe token cost waste, high API latency, and malicious prompt injection exploits designed to leak confidential system instructions.
To maintain financial efficiency and unshakeable security, modern enterprises deploy Enterprise AI Gateways with Semantic Routing & Prompt Firewall Layers.
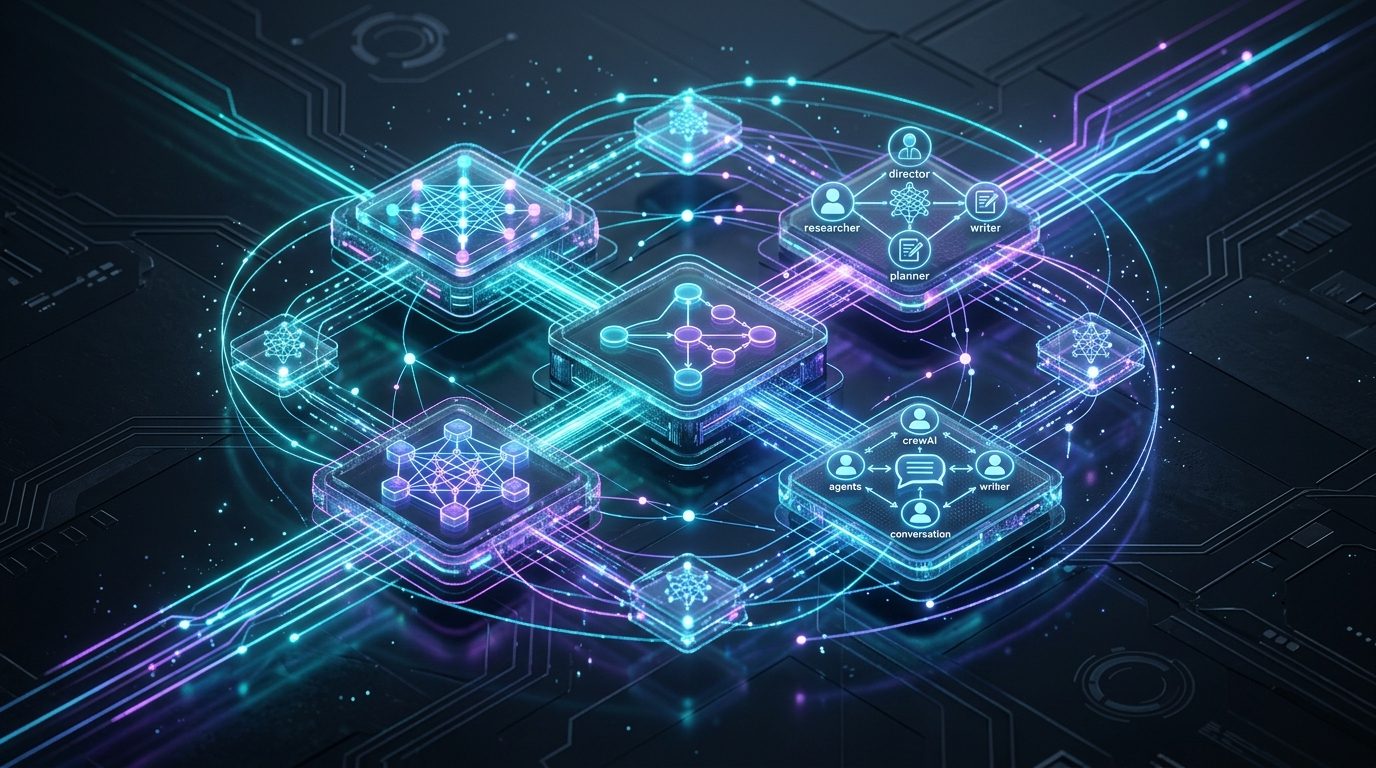
A semantic gateway intercepts every incoming user prompt, checks if a similar question was answered recently (semantic caching), blocks jailbreak attacks, and routes simple queries to fast, cheap models (like GPT-4o-mini or Claude 3 Haiku) while reserving expensive frontier models only for complex reasoning tasks.
This executive guide outlines the technical architecture of enterprise AI gateways, prompt firewalls, and development investment in both $ USD and ₹ INR (Rupees) without any code.
1. Direct LLM Calls vs. Devzuno Semantic AI Gateway
1. Direct LLM API Calls
Cost Inefficient- • **100% Token Waste:** Identical questions query expensive LLMs repeatedly
- • **Zero Security Barrier:** Vulnerable to direct prompt injections and system jailbreaks
- • **One-Size-Fits-All:** Every simple FAQ query hits expensive flagship models
- • **Single Point of Failure:** An outage in OpenAI or Anthropic takes down your entire app
2. Devzuno Semantic AI Gateway
60% Cost Reduction- • **Instant Semantic Cache:** 35% of repetitive queries answered in 5ms at $0 cost
- • **Prompt Injection Firewall:** Blocks toxic inputs and PII leaks before reaching models
- • **Intelligent Model Router:** Directs queries dynamically to the lowest-cost capable model
- • **Automated Multi-Vendor Failover:** Instantly reroutes traffic if an upstream provider fails
2. Measurable Financial Impact of an Enterprise AI Gateway
Monthly Cost Comparison at 250,000 Enterprise Queries/Month
3. Enterprise Prompt Gateway Development Pricing (USD & INR)
$8,500 – $18,000
₹7 Lakhs – ₹15 Lakhs
Redis semantic caching layer, multi-provider API key rotation (OpenAI/Anthropic/Gemini), and basic failover in 4 weeks.
$20,000 – $45,000
₹16.5 Lakhs – ₹37 Lakhs
Prompt injection guardrails (Llama Guard), automated PII redaction, dynamic cost-complexity model router, and analytics telemetry.
$120 – $450 / mo
₹10,000 – ₹37,500 / mo
Dedicated cloud server cluster, automated SSL, SOC-2 audit logs, and zero third-party telemetry data leakage.
4. Secure & Scale Your AI Infrastructure with Devzuno
Slash AI token expenditures and secure your corporate models against emerging cyber threats.
At Devzuno Technologies, our senior AI security engineers build high-speed semantic routing gateways that optimize AI speed, cost, and reliability.
👉 Request an AI Gateway Architecture Session with Devzuno today.